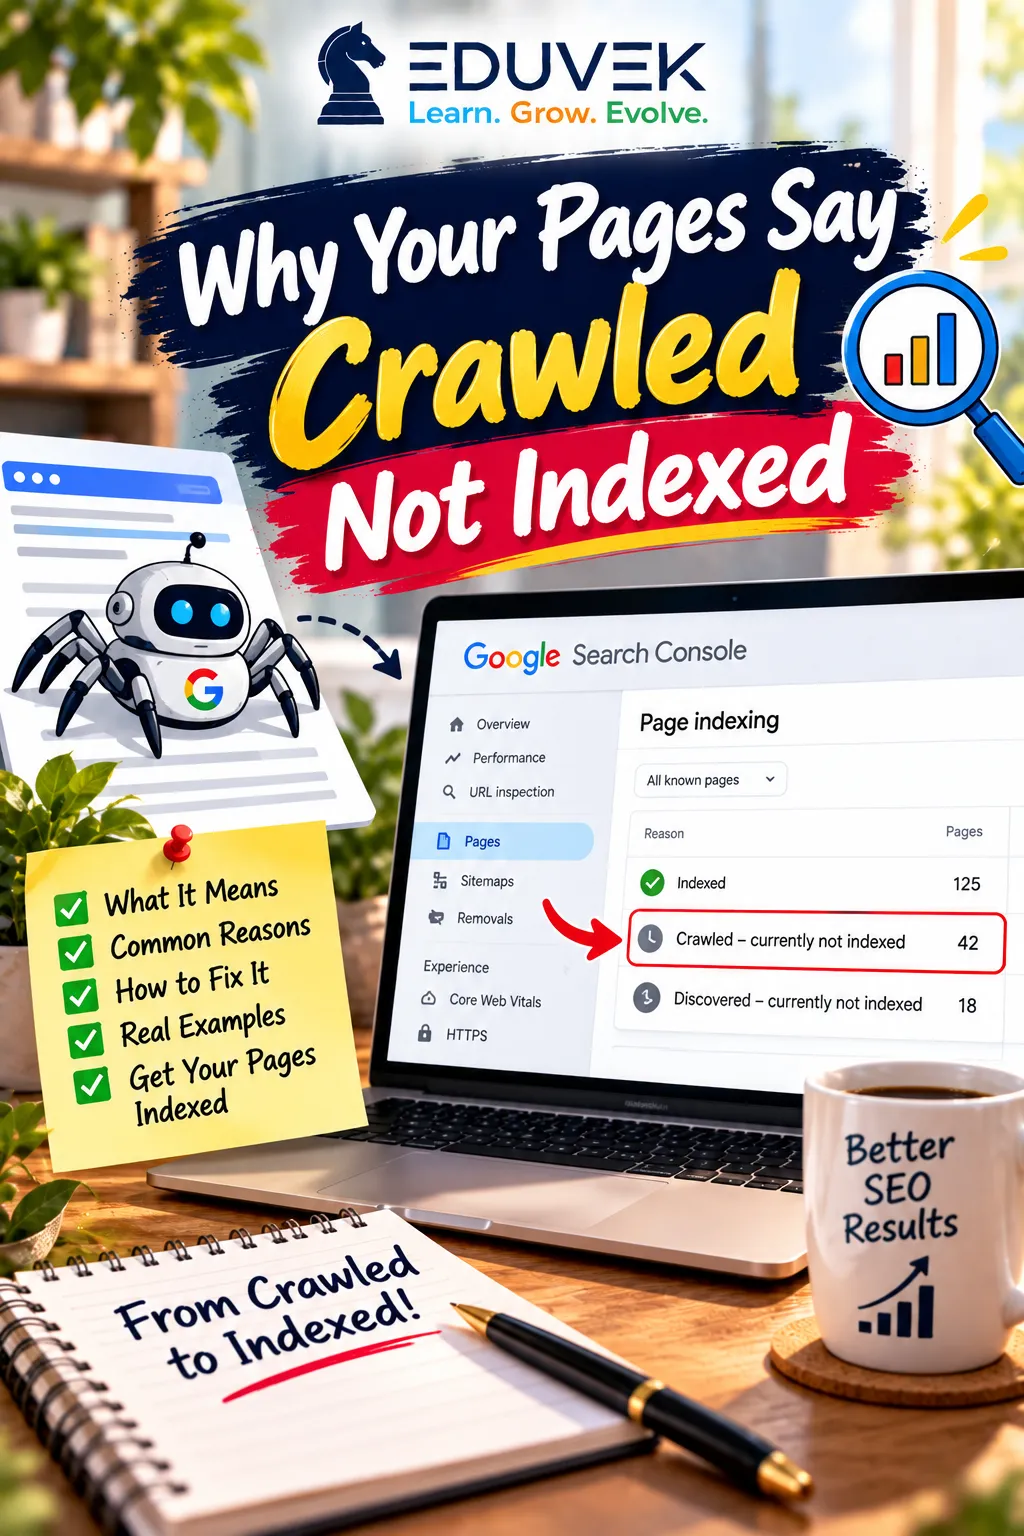
You open Google Search Console and see it: "Crawled – currently not indexed." Google visited the page and then chose not to add it to the index.
It's confusing precisely because nothing is technically "broken." Here's what the status is really telling you.
What it actually means
Google crawled the page but decided — for now — that it isn't worth indexing. It's a quality and priority signal, not an error. Google is effectively saying "we've seen this, and we're not convinced it earns a place in results yet."
Common causes
It usually comes down to one of these:
- Thin or low-value content.
- Pages that are near-duplicates of each other.
- Large sets of templated, thin pages that look mass-produced.
- Weak internal linking, so the page seems unimportant.
- A new or low-authority site, or simply a crawl backlog that resolves with time.
What it is NOT
This usually isn't a `robots.txt` or `noindex` block — those show up as different statuses. The page is technically accessible; the issue is that Google isn't persuaded it's worth indexing.
How to earn the index
Deepen the page so it genuinely answers its query better than what's already out there; consolidate near-duplicates into one strong page instead of several weak ones; add internal links from your more established pages so the page reads as important; and make sure it clearly deserves a reader's time. Then request indexing and give Google a chance to re-evaluate.
Be patient, and prioritise: Google revisits pages over time, and thin pages can get indexed once they improve — or once the whole site earns more trust. Spend your effort on the pages that genuinely deserve to rank.